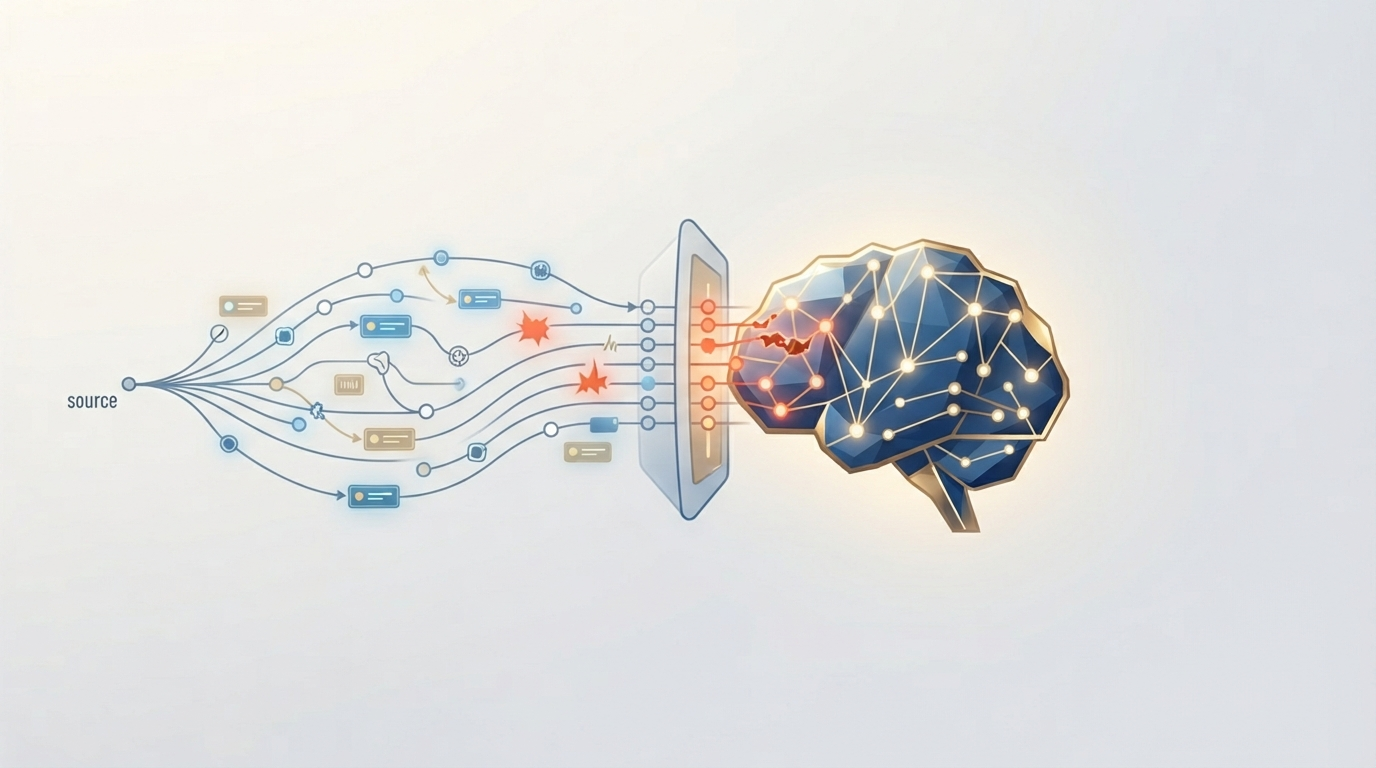
Every generative AI failure that makes headlines — a hiring tool that quietly discriminated, a chatbot that fabricated a legal citation, a model that leaked something it shouldn’t have known — traces back to the same root cause once you dig past the headline. It’s not that the model is broken. It’s that the data underneath it was flawed, incomplete, unrepresentative, or handled carelessly, and the model faithfully reproduced whatever it was given. Understanding these problems at the data layer, not just the model layer, is the actual difference between deploying generative AI responsibly and deploying it blindly.
Data Quality Is the Foundation Problem Everything Else Sits On
Generative AI models are only as reliable as the data they’re trained on, and most organizations dramatically underestimate how messy their real data actually is.
What “Bad Data” Actually Looks Like in Practice
This rarely means obviously wrong information. More often it’s duplicate records, missing fields, inconsistent formatting across systems, and outdated entries sitting alongside current ones — the unglamorous mess every organization accumulates over years of using different tools that were never designed to talk to each other. A model trained on this kind of data doesn’t fail loudly; it produces answers that are subtly, confidently wrong.
Why This Fails Quietly Instead of Loudly
The dangerous part is that a generative model doesn’t know its training data was flawed — it has no mechanism for flagging “this answer is based on inconsistent source information.” It generates a fluent, confident response regardless of whether the underlying data actually supports it, which is precisely why data quality problems tend to surface only after a bad output causes real damage, not before.
Bias Isn’t a Bug — It’s an Inheritance
A model trained on historical data inherits whatever patterns existed in that history, including the ones nobody would defend if asked directly.
The Amazon Hiring Tool as a Cautionary Case
One of the most widely documented examples: Amazon built an internal hiring tool trained on a decade of past resumes, and the model learned to penalize resumes associated with women — not because anyone programmed it to, but because the historical hiring data it learned from reflected years of a male-dominated industry. Amazon scrapped the tool once the pattern was discovered, and the case remains one of the clearest illustrations of how bias enters a model invisibly, through data that looks neutral on the surface but encodes decades of real-world inequality underneath.
Why Fixing This Isn’t a One-Time Task
Bias mitigation isn’t a checkbox you complete once during model training — it requires ongoing auditing of outputs across different demographic groups, deliberately diversifying training sources, and building feedback mechanisms that catch skewed patterns after deployment, not just before it. Bias that wasn’t visible in testing has a way of surfacing once a model meets the full diversity of real-world use.
Privacy Is a Genuine Tightrope, Not a Solved Problem
Generative AI improves with more data, and more data almost always means more sensitive information somewhere in the pipeline.
The Regulatory Landscape Has Gotten Considerably Harder
Organizations now navigate GDPR, CCPA, India’s DPDP Act, HIPAA for anything touching health data, and the EU AI Act’s requirements simultaneously — a genuinely different compliance burden than existed even three years ago, and one that varies by jurisdiction in ways that don’t align neatly with how global companies actually operate.
Techniques That Are Actually Working
Federated learning — training a model across many devices without the raw data ever leaving those devices — is one real technical answer, used in products like predictive keyboards specifically to improve suggestions without centralizing users’ private typing data on a single server. Differential privacy, which adds carefully calibrated statistical noise to training data, is another genuine approach, letting a model learn general patterns without being able to reconstruct any individual’s specific data point.
Where Compliance Failures Actually Cost Companies
Missing governance controls doesn’t just risk a regulatory fine — it slows adoption internally, since teams become reluctant to trust or expand a system they can’t confidently say handles data safely, and rebuilding that internal trust after a breach takes considerably longer than preventing it would have.
Confident Wrong Answers Are Harder to Catch Than Obviously Wrong Ones
This is arguably the least understood data-related challenge, because it doesn’t look like a data problem on the surface.
The Confidence-Accuracy Mismatch
Generative models produce fabricated information — commonly called hallucination — with the exact same fluent, confident tone as accurate information. Independent evaluations have found meaningful error rates even in advanced models specifically on tasks requiring precise factual recall, and there’s no built-in signal in the output itself distinguishing a well-supported claim from an invented one.
Why This Traces Back to Data, Not Just Model Design
Hallucination rates correlate directly with gaps or thinness in training data on a given topic — a model asked about something well-represented in its training data tends to perform far more reliably than one asked about a narrow or underrepresented subject, where it’s more likely to generate a plausible-sounding guess rather than admit uncertainty.
Integration Problems Are a Data Problem Wearing an Engineering Costume
Connecting a generative AI system to an organization’s actual, existing data infrastructure is rarely as simple as it looks in a vendor demo.
The Silo Problem
Most enterprise data sits scattered across email systems, shared drives, CRM notes, and chat logs, in wildly inconsistent formats — a majority of enterprise information is estimated to be unstructured, which is precisely the kind of data generative systems struggle to reliably ingest and reason over without significant preprocessing.
What Retrieval-Augmented Generation Actually Requires
Techniques like retrieval-augmented generation (RAG), which let a model pull from a live, current knowledge base rather than relying solely on its static training data, depend entirely on that live data source being clean, current, and correctly structured — a RAG system pointed at messy source data just produces confidently wrong answers faster, not more accurate ones.
What This Actually Means for Anyone Deploying These Systems
None of these challenges are reasons to avoid generative AI — they’re reasons to treat the data layer with the same seriousness usually reserved for the model itself. A well-chosen model fed poor data will underperform a modest model fed clean, well-governed data, nearly every time. According to a broad academic survey of generative AI and large language model challenges, bias, interpretability, and data-related reliability issues remain among the most actively researched open problems in the field — which is a useful reminder that these aren’t solved problems with a known fix waiting to be applied; they’re active, ongoing engineering and governance work.
Frequently Asked Questions
What is the biggest data challenge generative AI faces?
Data quality is generally considered the foundational issue, since poor, inconsistent, or incomplete data undermines every downstream capability — bias mitigation, hallucination reduction, and reliable integration all depend on the underlying data being sound first.
Can generative AI bias actually be fixed?
It can be meaningfully reduced through diversified training data, fairness-aware training techniques, and ongoing output auditing, but it isn’t a one-time fix — bias mitigation requires continuous monitoring as a model meets new, real-world use cases after deployment.
Why does generative AI sometimes sound confident about wrong information?
Because the model generates fluent text regardless of whether the underlying data actually supports the claim — there’s no built-in mechanism distinguishing a well-supported answer from a fabricated one, which is why hallucinated content reads with the same tone as accurate content.
What is federated learning, and why does it matter for AI privacy?
It’s a training method where a model learns across many individual devices without the raw data ever being centralized on one server — a genuine technical answer to improving AI while limiting how much sensitive personal data is exposed in the process.
Why is connecting generative AI to existing business data so difficult?
Because most enterprise data is unstructured and scattered across disconnected systems in inconsistent formats — techniques like retrieval-augmented generation can bridge this, but only when the underlying data source is clean and well-organized to begin with.
The uncomfortable pattern across every challenge here is the same one: none of it is really about the AI. It’s about whether the data feeding it was ever actually ready for the job being asked of it — and that’s a question worth answering honestly before deployment, not after something goes wrong in production.